The Unseen Guardians: Proactive Problem Identification
You know the feeling. That gut-wrenching dread as you navigate to your website, only to be met with a blank screen, a cryptic error message, or an infuriatingly slow loading spinner. Your business grinds to a halt, customer trust erodes, and revenue slips away. What if there was a way to significantly reduce the chances of this nightmare scenario? Welcome to the world of server monitoring, where proactive vigilance transforms potential catastrophes into mere hiccups. At its core, server monitoring is about having your finger on the pulse of your digital infrastructure, constantly gathering data, and interpreting the subtle signs of impending trouble long before they manifest as outright downtime. It’s an investment in foresight, a commitment to stability, and ultimately, a safeguard for your online presence.
The Art of Early Warning Systems
Imagine a complex machine, humming along, performing its tasks flawlessly. But beneath the surface, a tiny bearing is starting to wear, a small leak is developing, or a circuit is drawing slightly too much power. If left unchecked, these minor anomalies will inevitably escalate into a major breakdown. Your website servers are no different. They are intricate ecosystems of hardware, software, and network connections, all interdependent. Server monitoring acts as your early warning system, detecting these subtle deviations from baseline performance before they become critical. It’s not about waiting for a crash; it’s about predicting one and taking corrective action. This predictive capability is where the real value lies, allowing you to schedule maintenance, reallocate resources, or investigate potential vulnerabilities without disrupting user experience.
Key Metrics for a Healthy Server
What exactly are these “subtle signs” that monitoring tools look for? They are a rich tapestry of metrics, each telling a piece of the server’s story. Understanding these key indicators is fundamental to effective monitoring. CPU utilization, for instance, tells you how hard your server’s brain is working. Consistently high CPU usage, especially during off-peak hours, might indicate an inefficient application, a runaway process, or even a malicious attack. Memory usage is another critical metric, revealing how much RAM your server is consuming. Swapping, where the server uses hard disk space as virtual memory due to insufficient RAM, is a clear sign of memory pressure and will drastically slow down performance. Disk I/O (Input/Output) provides insight into how quickly your server can read and write data to its storage devices. Slow disk I/O can bottleneck an otherwise powerful server, leading to delays in serving web pages or processing database queries. Network traffic metrics, including bandwidth usage, packet loss, and latency, are crucial for understanding how data flows in and out of your server. High packet loss or latency can indicate network congestion or connectivity issues, impacting user access. Beyond these foundational metrics, monitoring also extends to specific services running on your server, such as web servers (Apache, Nginx), database servers (MySQL, PostgreSQL), and email servers. Are they running? Are they responding? Are they processing requests efficiently? Each component has its own set of health indicators that contribute to the overall picture of server well-being.
Baselines and Anomaly Detection
Simply collecting data isn’t enough; you need context. This is where the concept of baselines becomes invaluable. A baseline represents the normal, healthy operating parameters for your server under typical load conditions. Once you establish a baseline, any significant deviation from these norms becomes an anomaly. For example, if your server’s CPU utilization typically hovers around 20-30% during business hours, a sudden jump to 80-90% for an extended period is a clear anomaly that warrants immediate investigation. Monitoring tools employ various algorithms, from simple threshold-based alerts to more sophisticated machine learning techniques, to detect these anomalies. Thresholds are straightforward: if a metric exceeds or falls below a predefined value, an alert is triggered. While effective, fixed thresholds can sometimes generate false positives or negatives if not carefully calibrated. Machine learning, on the other hand, can learn your server’s unique behavior patterns over time, adapting to natural fluctuations and identifying more subtle deviations that might go unnoticed by static thresholds. This adaptive approach leads to more intelligent and actionable alerts, reducing alert fatigue and focusing your attention on genuine problems.
In addition to understanding how server monitoring reduces unexpected website downtime, it’s essential to consider the hosting environment that supports your website. A related article that provides valuable insights on this topic is titled “What is Shared Hosting: Is It Good for You?” This article explores the benefits and drawbacks of shared hosting, helping you make informed decisions about your website’s performance and reliability. You can read it here: What is Shared Hosting: Is It Good for You?.
Optimizing Performance and User Experience
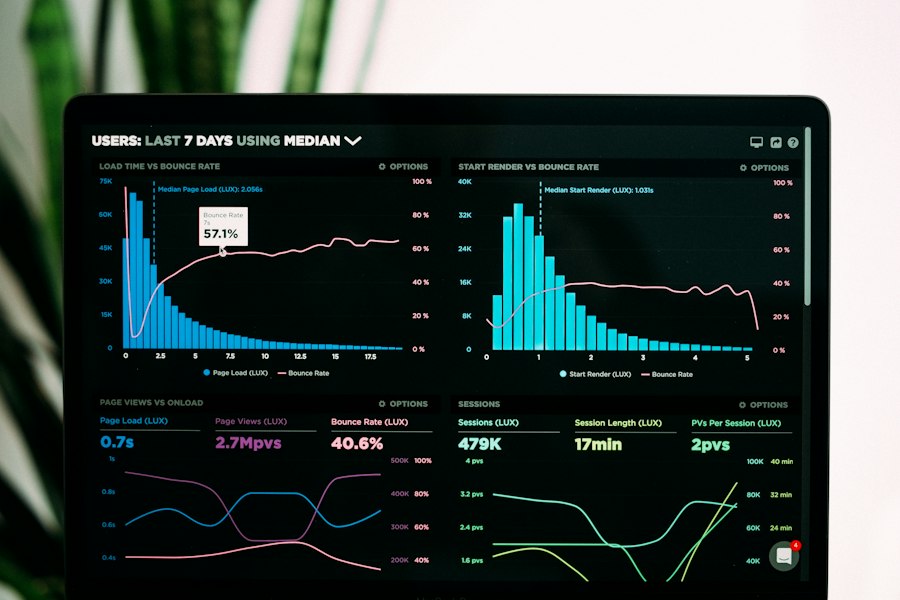
Beyond preventing outright crashes, server monitoring plays a pivotal role in optimizing your website’s performance and, by extension, the user experience. A slow website is a frustrating website, leading to high bounce rates, decreased engagement, and ultimately, lost opportunities. In today’s fast-paced digital landscape, users expect instant gratification, and even a few seconds of delay can significantly impact their perception of your brand. Server monitoring provides the granular data necessary to identify performance bottlenecks and make informed decisions about resource allocation, code optimization, and infrastructure scaling.
Pinpointing Performance Bottlenecks
Think of your website as a chain, where every component contributes to its overall strength. A single weak link can compromise the entire structure. Server monitoring helps you identify these weak links, pinpointing exactly where performance is suffering. Is it a slow database query? Is your web server struggling to handle the current volume of requests? Is a particular script consuming excessive CPU cycles? Without monitoring, you might be left guessing, making changes based on intuition rather than data, which can often lead to wasted effort or even introduce new problems. For example, if you observe high disk I/O alongside slow page load times, it suggests that your database might be reading and writing data inefficiently. This could prompt you to investigate database indexing, query optimization, or even consider upgrading to faster storage. Similarly, if memory usage is consistently high and swapping is occurring, it’s a strong indicator that your server lacks sufficient RAM for its current workload, necessitating a memory upgrade or a review of memory-intensive applications. By correlating various metrics, monitoring tools help you piece together the puzzle of performance issues, leading to targeted and effective solutions.
Resource Utilization and Capacity Planning
Effective resource management is crucial for both performance and cost efficiency. Server monitoring provides a clear picture of how your server resources (CPU, RAM, disk, network) are being utilized. Are you consistently under-utilizing resources, meaning you’re paying for capacity you don’t need? Or are you frequently hitting resource limits, indicating that your server is struggling to keep up with demand? This data is invaluable for capacity planning. If you anticipate a surge in traffic due to a marketing campaign or a seasonal event, monitoring data allows you to proactively scale your infrastructure. You can add more RAM, upgrade your CPU, or even provision additional servers before your existing resources become overwhelmed. Conversely, if monitoring reveals consistent underutilization, you might consider consolidating servers or downsizing your instance, leading to cost savings. Without this data, capacity planning becomes a risky guesswork, either leading to overspending on unnecessary resources or suffering performance degradation due to insufficient capacity. It’s about striking the right balance, ensuring your infrastructure is adequately provisioned to meet current and future demands without breaking the bank.
Impact on SEO and User Engagement
The speed and reliability of your website have a direct impact on its search engine optimization (SEO) and user engagement. Search engines like Google prioritize fast-loading websites that offer a smooth user experience. A slow website can negatively affect your search rankings, making it harder for potential customers to find you. Moreover, users are less likely to stay on a slow website, leading to higher bounce rates and reduced time on site. This, in turn, signals to search engines that your website may not be providing a good user experience, further impacting your rankings. Server monitoring helps you maintain optimal website performance, which translates into better SEO and improved user engagement. By ensuring your website loads quickly and is always available, you create a positive impression, encourage longer visits, and ultimately drive more conversions. It’s a virtuous cycle: a well-monitored, high-performing server leads to better SEO, which leads to more traffic, which leads to more business. Ignoring server performance is akin to building a beautiful storefront but having a perpetually closed door – no one can get in.
Security and Compliance Posture
While often associated with performance, server monitoring also plays a critical, albeit sometimes overlooked, role in maintaining your server’s security and ensuring compliance with various regulations. In an era of escalating cyber threats and stringent data protection laws, neglecting server security can have devastating consequences, ranging from data breaches and financial penalties to reputational damage. Server monitoring acts as a watchful guardian, providing visibility into potential security vulnerabilities and suspicious activities.
Detecting Malicious Activity
One of the most crucial security functions of server monitoring is its ability to detect unusual patterns that might indicate a cyberattack. This could include sudden spikes in outbound network traffic, which could signal a server being used for a Denial-of-Service (DoS) attack or data exfiltration. Unexpected changes to critical system files or configurations, particularly those associated with web server settings or user permissions, can be a red flag for unauthorized access or tampering. Repeated failed login attempts, especially from unusual IP addresses, might indicate a brute-force attack targeting your server. Monitoring logs for specific error messages or security warnings generated by firewalls, intrusion detection systems, and antivirus software can provide early warnings of malicious activity. By correlating these various indicators, monitoring tools can piece together a picture of a potential breach, allowing you to react swiftly and mitigate the damage. Early detection is paramount in cybersecurity; the faster you can identify and respond to an attack, the less impact it will have.
Identifying Vulnerabilities and Misconfigurations
Beyond active attacks, server monitoring helps you identify inherent vulnerabilities and misconfigurations that attackers could exploit. For example, monitoring for outdated software versions of your operating system, web server, or database server is crucial. Attackers often target known vulnerabilities in older software. Regular checks for open ports that shouldn’t be accessible to the public, or services running with elevated privileges unnecessarily, can expose critical attack surfaces. Monitoring user accounts for inactive or unauthorized accounts, and regularly reviewing permissions, helps prevent privilege escalation attacks. Furthermore, configuration drift, where server settings gradually deviate from a secure baseline over time, can introduce vulnerabilities. Monitoring tools can track configuration changes and alert you to any deviations that might compromise security. Proactive identification and remediation of these vulnerabilities are far more effective than reacting to a breach after it has occurred. It’s about patching the holes before the ship starts taking on water.
Ensuring Regulatory Compliance
Many industries are subject to strict regulatory compliance standards, such as GDPR, HIPAA, PCI DSS, and SOC 2. These regulations often mandate specific security controls, auditing requirements, and data retention policies. Server monitoring tools can be instrumental in demonstrating compliance. They provide comprehensive audit trails of server activity, including who accessed what, when, and from where. This logging capability is essential for forensic analysis in case of a security incident and for demonstrating adherence to regulatory requirements. For example, PCI DSS (Payment Card Industry Data Security Standard) requires robust logging and monitoring of all system components that store, process, or transmit cardholder data. Server monitoring ensures that these logs are collected, retained, and regularly reviewed, providing the necessary evidence for compliance audits. Failing to meet these compliance requirements can result in significant fines, legal action, and a severe blow to your organization’s reputation. Monitoring helps you proactively meet these obligations, reducing the risk of non-compliance.
Streamlining Incident Response and Recovery
No matter how robust your monitoring and preventative measures are, incidents will inevitably occur. Hardware can fail, software can glitch, and human error is always a factor. The true measure of a resilient system isn’t whether it experiences problems, but how quickly and effectively it can recover. Server monitoring dramatically streamlines incident response and accelerates recovery times, minimizing the duration and impact of any downtime.
Rapid Alerting and Notification
The immediate benefit of server monitoring in incident response is its ability to provide rapid alerts and notifications. When a critical metric crosses a threshold or an anomaly is detected, monitoring tools don’t just log the event; they actively notify the relevant personnel. This can be through email, SMS, push notifications to mobile apps, or integration with incident management platforms like PagerDuty or Opsgenie. The key is to ensure that the right people are informed at the right time, with sufficient context to understand the severity and nature of the problem. Instead of users reporting your website is down, your IT team is already aware and investigating, often before the first customer even notices. This significantly reduces the Mean Time To Detect (MTTD), which is the first crucial step in any incident response process. The sooner you know about a problem, the sooner you can begin to resolve it.
Diagnostic Data for Faster Troubleshooting
Once an alert is received, the next challenge is to diagnose the root cause of the problem. Without comprehensive monitoring data, this can be a painstaking and time-consuming process, involving manually checking logs, running diagnostic commands, and making educated guesses. Server monitoring provides a wealth of diagnostic data that dramatically accelerates troubleshooting. When an alert fires, it’s typically accompanied by context: which metric triggered the alert, its current value, and historical trends. Furthermore, integrated monitoring solutions can provide dashboards that correlate various metrics, allowing engineers to quickly see if a CPU spike coincided with a database slowdown, or if network latency increased at the same time as error rates on the web server. This holistic view helps engineers pinpoint the exact component or service that is failing, reducing the Mean Time To Resolve (MTTR). Instead of spending hours sifting through logs, they can quickly narrow down the problem, leading to a much faster resolution and minimal disruption to users.
Post-Mortem Analysis and Prevention
After an incident is resolved, the learning process truly begins. A post-mortem analysis, often called a root cause analysis, is essential for understanding why the incident occurred and how similar problems can be prevented in the future. Server monitoring data is invaluable for this analysis. By reviewing historical metrics, logs, and alerts leading up to the incident, you can reconstruct the sequence of events, identify contributing factors, and understand the full impact. For instance, if an incident was caused by a memory leak in a new application deployment, monitoring data can show the gradual increase in memory consumption over time, confirming the issue. This data helps answer critical questions: Was the monitoring system configured correctly to detect this problem earlier? Were the thresholds appropriate? Was there sufficient capacity? This retrospective analysis feeds directly back into improving your monitoring setup, refining alert configurations, enhancing your infrastructure, and optimizing your applications, thereby strengthening your overall system resilience and reducing the likelihood of recurrence. It’s a continuous feedback loop that drives continuous improvement.
Effective server monitoring is crucial for minimizing unexpected website downtime, as it allows administrators to identify and address issues before they escalate. For those interested in understanding the broader implications of web hosting, you might find it helpful to explore how different hosting models can impact performance. A related article discusses the intricacies of reseller hosting and its operational mechanics, which can provide valuable insights into how hosting choices affect website reliability. You can read more about it in this informative article.
Cost Savings and Business Continuity
| Metric | Description | Impact on Website Downtime | Example Value |
|---|---|---|---|
| Average Detection Time | Time taken to detect server issues | Faster detection reduces downtime duration | Less than 1 minute |
| Response Time | Time taken to respond after issue detection | Quicker response minimizes downtime impact | Under 5 minutes |
| Uptime Percentage | Percentage of time the website is operational | Higher uptime means less unexpected downtime | 99.95% |
| Number of Downtime Incidents | Count of unexpected outages in a given period | Monitoring helps reduce incident frequency | 2 per month |
| Mean Time to Recovery (MTTR) | Average time to restore service after failure | Lower MTTR reduces total downtime | 10 minutes |
| Server Resource Utilization | CPU, memory, and disk usage metrics | Helps prevent overload-related downtime | CPU |
| Error Rate | Frequency of server errors (e.g., 500 errors) | Monitoring reduces error spikes causing downtime | Less than 0.1% |
While server monitoring requires an initial investment in tools and expertise, the long-term benefits in terms of cost savings and ensuring business continuity far outweigh the expenditures. Downtime is incredibly expensive, not just in terms of lost revenue, but also in terms of damaged reputation, reduced productivity, and potential penalties. By effectively reducing unexpected downtime, server monitoring becomes a strategic asset that directly contributes to your bottom line.
Mitigating Revenue Loss
The most immediate and tangible cost of unexpected website downtime is lost revenue. For e-commerce businesses, every minute your site is down translates directly into lost sales. For service-based businesses, it means missed appointments, inability to process inquiries, and a halt in service delivery. Even for informational websites, downtime can lead to lost advertising revenue or inability to capture leads. Consider a busy online retailer that generates thousands of dollars in sales per hour. An hour of downtime could mean tens of thousands in lost revenue. A full day? Potentially hundreds of thousands. Server monitoring drastically reduces the frequency and duration of these outages, directly preserving your revenue streams. It ensures that your online storefront is always open for business, minimizing the financial impact of technical glitches.
Protecting Brand Reputation and Customer Trust
Beyond direct financial losses, unexpected downtime severely damages your brand reputation and erodes customer trust. In today’s competitive landscape, customers have countless alternatives, and a single negative experience can drive them away permanently. A website that is frequently down or notoriously slow conveys an image of unreliability and unprofessionalism. Customers will question your ability to deliver, and negative word-of-mouth can spread rapidly, further damaging your brand. Server monitoring, by ensuring high availability and consistent performance, helps you build and maintain a reputation for reliability and professionalism. When customers know they can consistently rely on your website, their trust deepens, leading to increased loyalty and repeat business. This intangible asset – your brand’s reputation – is often more valuable than immediate revenue, and server monitoring is a critical tool for protecting it.
Avoiding Penalties and SLA Breaches
For businesses operating under Service Level Agreements (SLAs) with their clients, unexpected downtime can trigger contractual penalties. Many contracts stipulate minimum uptime percentages, and failing to meet these can result in significant financial penalties, service credits, or even contract termination. Server monitoring provides the necessary data to demonstrate compliance with these SLAs and, more importantly, helps prevent breaches in the first place. By proactively identifying and resolving issues, you minimize the risk of falling below your agreed-upon uptime thresholds. Even without formal SLAs, internal agreements or expectations regarding system availability are common. Monitoring helps ensure you meet these internal benchmarks, maintaining operational efficiency and internal stakeholder satisfaction. The costs of an SLA breach can quickly escalate, making the investment in server monitoring a prudent financial decision.
Maximizing IT Team Productivity
Without effective server monitoring, your IT team spends an inordinate amount of time reactively troubleshooting problems after they’ve already impacted users. This “firefighting” approach is inefficient, stressful, and prevents your team from focusing on strategic initiatives and proactive improvements. They are constantly scrambling to put out fires rather than preventing them. Server monitoring shifts your IT team from a reactive to a proactive stance. With early warnings and detailed diagnostic data, they can address issues before they become critical, often during off-peak hours or as part of scheduled maintenance. This reduces the pressure, improves morale, and allows them to dedicate more time to innovation, development, and system enhancements, ultimately leading to greater overall productivity and a more resilient infrastructure. It’s about working smarter, not just harder, and empowering your IT professionals to be architects of stability rather than perpetual emergency responders.

Add comment