
The Foundation of Resilient Computing
You’re navigating a world powered by data. Every click, every stream, every transaction relies on servers that are constantly processing information. For this intricate web of digital activity to function seamlessly, server stability and peak performance are paramount. Modern data centers aren’t just big rooms filled with computers; they are sophisticated, highly engineered environments designed from the ground up to ensure your applications run reliably and at lightning speed. You might not see them, but these centers are the unsung heroes maintaining the digital services you depend on every day, constantly striving to eliminate downtime and maximize efficiency.
Consider the journey of a single request – perhaps you’re checking your bank balance or streaming a high-definition movie. That request travels to a server, which processes it and sends back the information you need. If that server is unstable, or slow, your experience suffers. Modern data centers tackle these challenges head-on through a multi-faceted approach, integrating advanced hardware, intelligent software, and robust infrastructure to create an ecosystem where servers can thrive. You’ll find that the improvements aren’t incremental; they are transformational, addressing everything from the microscopic level of individual chip performance to the macroscopic level of global network redundancy. You are, in essence, benefiting from a continuous cycle of innovation focused on making your digital life smoother, faster, and more secure.
The Evolution of Server Stability
You remember the early days of computing, perhaps when a single server failure could bring down an entire department. The approach to stability was reactive, often involving manual intervention and lengthy recovery times. Today, that paradigm has shifted dramatically. You are now in an era where proactive measures, predictive analytics, and automated remediation are standard. This evolution wasn’t accidental; it was driven by the ever-increasing demands of a global, always-on economy. Businesses simply cannot afford downtime, and you, as a consumer, have come to expect uninterrupted service.
The journey began with basic redundancy – having a backup server ready to take over if the primary one failed. While a significant step, this often led to substantial failover times and data loss during the transition. You then saw the rise of virtualization, which allowed multiple virtual servers to run on a single physical machine, increasing hardware utilization but also adding layers of complexity to manage. Modern data centers build upon these foundations, integrating advanced technologies like software-defined networking, hyper-converged infrastructure, and AI-powered operations to achieve unprecedented levels of stability. You’re no longer just dealing with hardware; you’re dealing with an intelligent, self-optimizing system designed to prevent failures before they occur and recover almost instantaneously if they do.
The Need for Enhanced Performance
You’ve noticed it yourself: applications are more data-intensive, users expect real-time responses, and the volume of information being processed globally is astronomical. This relentless increase in demand puts immense pressure on server performance. A slow server isn’t just an inconvenience; it can lead to lost revenue for businesses, frustrated customers, and missed opportunities. Think about e-commerce during a peak shopping season – every millisecond of delay can translate into millions of dollars in lost sales.
The drive for enhanced performance isn’t solely about raw processing power, although that’s certainly a part of it. It’s about optimizing every component of the data path, from the speed of the storage to the efficiency of the network fabric. You’re looking at a holistic approach where bottlenecks are identified and eliminated, resources are allocated dynamically, and workloads are distributed intelligently. The goal is not just to make individual servers faster, but to make the entire data center operate as a single, highly efficient computing engine. This involves sophisticated workload balancing, intelligent caching, and the strategic deployment of specialized hardware like GPUs and FPGAs for specific computational tasks. You are, in essence, consuming services powered by an optimized symphony of hardware and software working in perfect concert.
In the ever-evolving landscape of technology, the stability of servers is crucial for maintaining optimal performance and user experience. A related article that delves into the importance of web performance is titled “Mastering Core Web Vitals: The New Key to Google Rankings.” This piece highlights how modern data centers, with their advanced infrastructure and efficient resource management, play a significant role in enhancing server stability, which in turn positively impacts website performance and search engine rankings. For more insights, you can read the article here: Mastering Core Web Vitals: The New Key to Google Rankings.
Advanced Cooling and Power Management
You might not immediately think of cooling and power as critical components for server stability and performance, but you’d be mistaken. These are foundational elements. Imagine a high-performance race car without an adequate cooling system or a reliable fuel delivery mechanism; it simply wouldn’t perform. Similarly, servers generate immense heat and require a consistent, clean power supply. Without sophisticated management of these two factors, your servers would overheat, experience brownouts, or fail prematurely, leading directly to instability and degraded performance. Modern data centers have elevated cooling and power management to a science, ensuring an optimal operating environment for every piece of hardware.
Precision Cooling Systems
You know that electronics generate heat, and servers, especially high-density racks, are veritable furnaces. Uncontrolled heat leads to thermal throttling, where processors intentionally slow down to prevent damage, directly impacting performance. Beyond throttling, excessive heat drastically reduces the lifespan of components, leading to increased failures and instability. Modern data centers employ an array of advanced cooling techniques that go far beyond simple air conditioning. You’re looking at intelligent systems designed for precision, efficiency, and scalability.
Hot and Cold Aisle Containment
You’ll often find data centers structured with hot and cold aisles. This simple yet highly effective method segregates the hot exhaust air from the cold intake air, preventing them from mixing. Servers are typically arranged with their fronts facing a “cold aisle” where cool air is supplied, and their rears facing a “hot aisle” where heated exhaust air is collected. This separation is then “contained” – either the cold aisle is capped, creating a plenum for cool air, or the hot aisle is enclosed to channel hot air directly back to the cooling units. By preventing hot air recirculation, you ensure that servers always receive the coldest possible air, maximizing cooling efficiency and minimizing energy waste. This precision ensures that your servers can operate at their peak clock speeds without being throttled due to rising temperatures.
Liquid Cooling Solutions
You might think of liquid cooling as something reserved for high-end gaming PCs, but it’s becoming increasingly prevalent in modern data centers, especially for ultra-dense server racks and specialized computational tasks. As server power densities continue to increase, traditional air cooling can struggle to keep up. Liquid, with its far superior thermal conductivity compared to air, offers a much more efficient way to dissipate heat. You’ll encounter several types:
- Direct-to-Chip Cooling: In this method, a liquid-cooled cold plate is attached directly to the hottest components, such as the CPU and GPU. A dielectric fluid circulates through these plates, drawing heat away before it can spread to the surrounding air. This allows these critical components to run cooler and maintain higher clock speeds, directly boosting performance and stability.
- Immersion Cooling: This is perhaps the most radical but highly effective method. Entire server racks or individual servers are submerged in a non-conductive, dielectric fluid. This fluid directly contacts all components, absorbing heat extremely efficiently. You might imagine a server “swimming” in liquid; this drastically improves cooling, reduces noise, and often eliminates the need for fans altogether, leading to lower power consumption and improved reliability. You benefit from servers running at consistently optimal temperatures, unlocking their full potential.
AI-Powered Environmental Controls
You’re no longer relying on static temperature settings. Modern data centers integrate AI and machine learning into their environmental control systems. Sensors strategically placed throughout the facility collect vast amounts of data on temperature, humidity, airflow, and power consumption. AI algorithms analyze this data in real-time to dynamically adjust cooling unit fan speeds, chiller output, and airflow dampers. This means that cooling resources are precisely allocated where and when they are needed, optimizing energy consumption while maintaining ideal operating temperatures. You get proactive adjustments that prevent hot spots from developing, ensuring a stable environment that reduces the risk of thermal-related failures and maximizes server uptime.
Robust Power Infrastructure
You can have the most advanced servers in the world, but if their power supply is unreliable, they are useless. Power stability is non-negotiable for data centers. Fluctuations, sags, spikes, and outages can all cause severe damage to hardware, corrupt data, and lead to significant downtime. Modern data centers are engineered with multiple layers of redundancy and protection to ensure an uninterrupted, high-quality power supply. You are looking at an infrastructure designed for resilience.
Uninterruptible Power Supplies (UPS)
You probably know what a UPS is for your home computer, but in a data center, these are industrial-strength systems. A data center UPS typically consists of large battery banks that can instantly provide power to servers the moment a utility power failure occurs. This “instant” power is critical because even a momentary flicker can cause servers to reboot or crash. The UPS acts as a buffer, smoothing out any minor fluctuations in the utility power, delivering clean, consistent power to your servers. This ensures that your applications continue to run without interruption during short power disturbances, preventing data loss and maintaining service availability.
Generator Backup Systems
You can’t run a whole data center on batteries for very long. For extended power outages, modern data centers rely on massive diesel or natural gas generators. These generators are designed to automatically start up and take over the data center’s power load within minutes of a sustained utility power failure. They are often tested regularly and kept fueled, ready to provide continuous power for days or even weeks if necessary. This multi-layered approach – UPS for instantaneous power and generators for long-term backup – ensures that your servers remain online even during significant grid failures, providing you with consistent access to services.
Redundant Power Distribution
You’ll find that power isn’t just supplied from one source. Modern data centers employ multiple, independent power feeds from the utility grid, often from different substations. Within the data center itself, power distribution is also highly redundant, frequently using “2N” or “N+1” configurations. This means there are at least two independent power paths (2N) to every server, or at least one more component than is minimally required (N+1) for each stage of power delivery. If one path fails, the other can immediately take over without any disruption. This elaborate redundancy minimizes single points of failure, ensuring that power always reaches your servers, contributing directly to their continuous operation and stability.
Intelligent Network Fabric and Connectivity
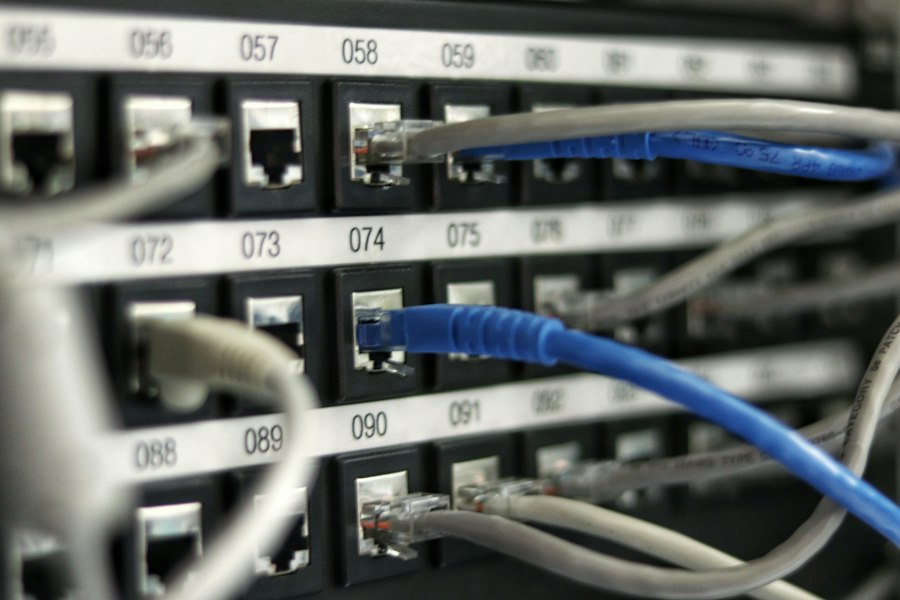
You can have the fastest servers and the most robust power, but without an intelligent and high-performance network, your data center is bottlenecked. The network fabric is the nervous system of the data center, connecting servers to storage, servers to other servers, and the entire data center to the outside world. Just as your brain relies on a fast and reliable network of neurons, your digital services rely on a network that can handle massive data volumes with minimal latency and maximum reliability. Modern data centers have invested heavily in creating a network infrastructure that is not only fast but also highly resilient and dynamically managed.
High-Bandwidth, Low-Latency Interconnects
You’re dealing with immense amounts of data moving between virtual machines, containers, and microservices. Traditional network architectures, with their hierarchical structures and potential bottlenecks, simply can’t keep up. Modern data centers employ flat, non-blocking network architectures designed for maximum throughput and minimal delay.
Spine-and-Leaf Architecture
You’ll frequently encounter a spine-and-leaf network topology in modern data centers. This design eliminates traditional three-tier networking complexities (core, distribution, access) by creating a highly interconnected, two-tier fabric. Leaf switches connect directly to servers, while spine switches connect all leaf switches. Every leaf switch connects to every spine switch, ensuring that any server can reach any other server with a maximum of two hops. This architecture provides predictable latency, high bandwidth, and massive scalability. As you need more capacity, you simply add more leaf or spine switches, without re-architecting the entire network. This direct, low-latency communication path is crucial for distributed applications, ensuring that components can talk to each other quickly and efficiently.
25/50/100 Gigabit Ethernet and Beyond
You’re no longer limited to 1 Gigabit Ethernet for server connectivity. Modern data centers have widely adopted 25 Gigabit Ethernet (GbE) as the standard for server uplinks, with 50 GbE and 100 GbE becoming common for uplinks between switches and for high-performance computing clusters. This massive increase in bandwidth ensures that the network doesn’t become a bottleneck, allowing servers to fully utilize their processing power and access data at unprecedented speeds. You experience faster application responses, quicker data transfers, and seamless operation even under heavy load. The continuous push for higher speeds directly translates to improved performance for all your data-intensive tasks.
InfiniBand and NVMe over Fabrics
You’ll find that for the most demanding workloads, such as AI/ML training, high-performance computing (HPC), and ultra-low-latency storage, traditional Ethernet, even at high speeds, might not be enough. InfiniBand provides extremely high bandwidth and ultra-low latency, often used for inter-node communication within HPC clusters where nanosecond-level delays matter. Furthermore, NVMe over Fabrics (NVMe-oF) allows servers to access remote NVMe-based storage (which is inherently very fast) over a network with near-local performance. This means your applications can leverage the speed of flash storage across the network without significant performance degradation, ensuring that I/O operations are no longer a bottleneck for your high-performance applications.
Software-Defined Networking (SDN) and Network Virtualization
You need a network that is as agile and dynamic as your virtualized and containerized workloads. Traditional networks, with their manual configurations and rigid structures, are ill-suited for the rapid deployment and scaling demands of modern cloud environments. This is where Software-Defined Networking (SDN) and network virtualization come into play.
Centralized Control and Automation
You benefit from SDN by centralizing network control. Instead of configuring individual network devices one by one, a central controller manages the entire network. This allows for automated provisioning, configuration, and management of network resources. Network policies can be defined globally and applied consistently across the entire data center, reducing human error and speeding up deployments. You can provision new network segments, adjust routing, and enforce security policies programmatically, making the network infrastructure as flexible as the virtualized servers it connects. This agility is crucial for continuous integration and continuous deployment (CI/CD) pipelines, enabling rapid application updates without manual network adjustments.
Microsegmentation for Enhanced Security and Stability
You’re increasingly concerned about security. SDN facilitates microsegmentation, a powerful security technique where network access is granted on a “least privilege” basis for individual applications or even workloads. Instead of a single firewall protecting the data center perimeter, microsegmentation creates granular security zones around each virtual machine or container. This means that if one server is compromised, the attacker’s ability to move laterally across the network (east-west traffic) is severely limited. This “zero-trust” approach enhances stability by containing potential breaches, preventing them from escalating into widespread outages or data compromises that could destabilize entire systems. You benefit from a more secure and inherently more stable computing environment.
Network Function Virtualization (NFV)
You’re seeing a shift from dedicated, proprietary hardware appliances (like firewalls, load balancers, and intrusion detection systems) to virtualized network functions running on standard servers. This is Network Function Virtualization (NFV). NFV allows these network services to be deployed, scaled, and managed entirely in software, offering greater flexibility and reducing hardware costs. You can spin up a new virtual firewall or load balancer in minutes, scale it up or down based on demand, and even move it to different servers without physical reconfiguration. This agility improves network resilience, as failing network functions can be automatically redeployed, contributing to overall server and application stability.
Robust Storage and Data Management
You can’t have reliable servers without reliable, high-performance storage. Data is the lifeblood of modern applications, and how it’s stored, accessed, and protected directly impacts server stability and performance. Imagine trying to run a complex database application if the disk it resides on is slow or unreliable; your server would constantly wait for data, leading to timeouts, errors, and a complete degradation of service. Modern data centers employ sophisticated storage solutions designed for speed, redundancy, and intelligent management.
High-Performance Storage Tiers
You’re operating in a world where not all data is created equal. Some data requires instantaneous access, while other data can tolerate slightly longer retrieval times. Modern data centers utilize a tiered storage approach to optimize both performance and cost.
All-Flash and Hybrid Storage Arrays
You’ll find that solid-state drives (SSDs) and Non-Volatile Memory Express (NVMe) drives are now standard for applications demanding the highest I/O performance. All-flash arrays (AFAs) consist entirely of these fast flash drives, providing incredibly low latency and high throughput, crucial for databases, transaction processing systems, and virtual desktop infrastructure (VDI). Hybrid storage arrays combine the speed of flash for frequently accessed “hot” data with the cost-effectiveness of traditional hard disk drives (HDDs) for “cold” data. Intelligent caching and tiering software automatically move data between these tiers based on access patterns, ensuring that your servers always have fast access to the data they need most, improving application responsiveness and overall stability.
Storage Area Networks (SANs) and Network-Attached Storage (NAS)
You’re likely interacting with data served from either a SAN or NAS. SANs provide block-level storage access, treating networked storage as if it were directly attached to the server. This is ideal for databases and applications requiring high performance and direct control over storage. NAS, on the other hand, provides file-level access and is excellent for file sharing, backups, and less performance-critical applications. Modern data centers deploy both, leveraging their respective strengths to meet diverse workload requirements. The underlying infrastructure for both typically involves high-speed Fibre Channel or iSCSI networks to ensure minimal latency for data access, preventing storage from becoming a performance bottleneck for your servers.
Data Protection and Redundancy
You know that data loss is catastrophic. Server stability isn’t just about preventing hardware failures; it’s also about ensuring data integrity and availability. Modern data centers implement multiple layers of data protection to guard against hardware failures, accidental deletion, and even site-wide disasters.
RAID and Erasure Coding
You’re probably familiar with RAID (Redundant Array of Independent Disks) configurations, which distribute data across multiple drives along with parity information to allow for data reconstruction in case of a drive failure. Modern storage systems often go beyond traditional RAID with more advanced techniques like erasure coding. Erasure coding breaks data into fragments and generates parity fragments, distributing them across a much larger set of storage devices. This offers significantly higher data redundancy and fault tolerance than traditional RAID, allowing for the loss of multiple drives without data loss, thus ensuring the continuous availability of data to your servers even in the face of significant hardware failures.
Snapshots and Replication
You’re benefiting from point-in-time copies of your data through snapshots. Snapshots allow for instant recovery of data to a previous state, which is invaluable for rolling back accidental deletions or recovering from corruptions. Beyond local protection, modern data centers employ replication technologies to continuously copy data to secondary storage systems, often in different physical locations. Synchronous replication ensures that data is written to both locations simultaneously, guaranteeing zero data loss (RPO=0) but introducing some latency. Asynchronous replication allows for a small amount of data loss but is more suitable for longer distances and less latency-sensitive applications. This geographical redundancy ensures that even if an entire data center suffers a catastrophic event, your data remains safe and accessible, allowing services to be restored quickly on alternate infrastructure.
Automated Backup and Archiving
You’re relying on sophisticated backup systems that automatically capture server configurations, operating systems, and application data. These backups are often tiered, with frequent incremental backups for quick recovery, and less frequent full backups for long-term retention. Archiving solutions are also used for data that needs to be retained for compliance or historical purposes but is rarely accessed, often moving it to more cost-effective cold storage. The automation of these processes minimizes human error and ensures that a recoverable version of your data is always available, drastically reducing the impact of potential data loss events on server stability and continuity of service.
In the quest for enhanced server stability, modern data centers are implementing innovative technologies and practices that significantly reduce downtime and improve performance. For those interested in exploring more about the challenges faced by online platforms, a related article discusses the common pitfalls in blogging and offers insights on how to navigate them effectively. You can read more about it in this informative piece on blogging mistakes. Understanding these challenges can provide valuable context for the importance of reliable server infrastructure in maintaining a successful online presence.
Automation and Orchestration for Operational Excellence
| Metric | Traditional Data Centers | Modern Data Centers | Improvement |
|---|---|---|---|
| Server Uptime | 95% | 99.99% | +4.99% |
| Mean Time Between Failures (MTBF) | 2000 hours | 10000 hours | +8000 hours |
| Mean Time to Repair (MTTR) | 4 hours | 30 minutes | -3.5 hours |
| Power Usage Effectiveness (PUE) | 2.0 | 1.2 | -0.8 |
| Automated Monitoring Coverage | 40% | 95% | +55% |
| Redundancy Level | N+1 | 2N | Higher redundancy |
| Cooling Efficiency | 70% | 90% | +20% |
| Server Density (servers per rack) | 20 | 40 | +100% |
You might think of data centers as primarily physical spaces, but increasingly, their efficiency and stability are driven by intelligence and automation. Manual operations are prone to human error, slow, and cannot keep up with the dynamic demands of modern cloud environments. Modern data centers leverage sophisticated automation and orchestration platforms to manage everything from server provisioning to incident response, dramatically improving reliability, performance, and operational efficiency.
Infrastructure as Code (IaC)
You’re moving away from manually configuring servers. With Infrastructure as Code (IaC), you define your entire infrastructure (servers, networks, storage, applications) in code files. These files are version-controlled, testable, and repeatable, just like application code.
Automated Server Provisioning
You can now provision new servers or entire application environments automatically using IaC tools. Instead of a multi-day manual process, a new server, configured exactly to specification, can be deployed in minutes. This consistency eliminates configuration drift and human error, which are common causes of instability. If a server fails, a new one can be spun up identically and automatically, ensuring rapid recovery and minimal downtime. This speed and consistency directly contribute to overall server stability and the agility to scale your services on demand.
Configuration Management and Idempotence
You ensure that servers remain in their desired state using configuration management tools. These tools continuously monitor server configurations and automatically apply necessary changes to bring them back into compliance with the defined standard. This idempotence means that applying the same configuration script multiple times will always result in the same desired state, preventing inconsistencies that could lead to instability or performance issues. You benefit from a uniform and predictable server environment, which is easier to troubleshoot and maintain, leading to higher reliability.
Orchestration and Workflow Automation
You’re not just automating individual tasks; you’re orchestrating complex workflows that span multiple systems and components. Orchestration platforms coordinate automated tasks across servers, networks, and storage to achieve a desired end-state for an application or service.
Dynamic Resource Allocation
You’re operating in environments where workloads fluctuate. Orchestration platforms can dynamically allocate resources (CPU, memory, storage, network bandwidth) to servers based on real-time demand. If an application suddenly experiences a spike in traffic, the orchestration system can automatically provision additional server instances, increase the resources allocated to existing ones, or migrate workloads to less congested servers. This proactive management prevents resource contention, ensuring that your applications always have the capacity they need to perform optimally and remain stable under varying loads.
Automated Incident Response
You’re minimizing the impact of potential issues through automated incident response. Monitoring systems detect anomalies or failures (e.g., a server experiencing high CPU load, a disk nearing capacity, or a network link failing). Orchestration platforms can then automatically trigger predefined actions:
- Restarting a service or an entire server.
- Isolating a faulty server from the network.
- Failing over to a redundant server.
- Provisioning a new replacement server.
- Notifying engineers of critical events.
This rapid, automated response significantly reduces mean time to recovery (MTTR), improving overall server stability and minimizing the disruption to your services. You get issues resolved faster, often before they even impact end-users.
Continuous Monitoring and Predictive Analytics
You can’t manage what you don’t measure. Modern data centers are saturated with sensors and monitoring tools that collect vast amounts of telemetry data from every component – servers, network devices, storage arrays, power units, and cooling systems.
Real-time Performance Monitoring
You’re benefiting from comprehensive, real-time dashboards that display key performance indicators (KPIs) for every server and application. This includes CPU utilization, memory consumption, disk I/O, network latency, and application-specific metrics. This granular visibility allows operations teams to identify performance bottlenecks, anticipate potential issues, and troubleshoot problems quickly. You get insights that enable proactive tuning and optimization, ensuring that your servers are always performing at their best.
Log Aggregation and Analysis
You’re dealing with millions of log entries generated by servers and applications every second. Modern data centers use centralized log aggregation systems that collect, parse, and analyze these logs. AI and machine learning algorithms can detect patterns, identify anomalies, and correlate events across different systems, often pinpointing the root cause of an issue much faster than manual inspection. This predictive capability allows operators to address potential problems before they escalate into full-blown outages, significantly enhancing server stability. You’re proactively fixing issues before they impact your services.
Predictive Maintenance
You’re moving from reactive repairs to predictive maintenance. By analyzing historical data from server hardware (e.g., fan speeds, temperatures, error rates for disks), AI algorithms can predict when components are likely to fail. This allows operations teams to proactively replace hardware during scheduled maintenance windows, preventing unexpected failures that could lead to server downtime. This foresight dramatically improves hardware reliability and overall server stability, ensuring that critical components are swapped out before they can cause a disruption.
In exploring the advancements in server stability within modern data centers, it’s also important to consider how these improvements can enhance the overall performance of online platforms. For instance, a well-optimized data center can significantly benefit e-commerce websites, ensuring they remain operational even during peak traffic times. You can read more about the importance of maintaining a blog for your e-commerce site and how it can contribute to its success in this insightful article here.
Enhanced Security and Compliance
You can’t talk about server stability and performance without addressing security. A compromised server is by definition unstable and unreliable; its performance can be degraded, and its data integrity is at risk. Moreover, compliance with various regulations (GDPR, HIPAA, PCI DSS, etc.) is non-negotiable for many businesses. Modern data centers integrate security and compliance as fundamental design principles, not as afterthoughts, creating a resilient and trustworthy environment for your data and applications.
Multi-Layered Security Approach
You’re protected by a defense-in-depth strategy, where multiple security controls are layered throughout the data center infrastructure. No single control is foolproof, but the combination of them creates a robust barrier against threats.
Physical Security
You might not see it, but the physical security of a modern data center is incredibly stringent. This includes perimeter fencing, 24/7 on-site security personnel, biometric access controls (fingerprint, iris scans), CCTV surveillance, and mantraps (two-door entry systems that only allow one door to open at a time). Only authorized personnel can access the facility and server rooms, preventing unauthorized physical tampering that could compromise server stability or data. You can rest assured that the physical environment housing your data is locked down.
Network Security
You’re safeguarded by sophisticated network security measures. This includes enterprise-grade firewalls, intrusion detection and prevention systems (IDPS), and DDoS mitigation services that filter malicious traffic before it reaches your servers. Encryption is ubiquitous, protecting data in transit (e.g., SSL/TLS) and at rest (e.g., disk encryption). Microsegmentation, as discussed earlier, confines potential threats to isolated network segments, limiting their ability to move laterally and preventing widespread server compromise. You’re operating within a securely segmented and constantly monitored network environment.
Host and Application Security
You’re protected at the server and application level. This involves hardening operating systems, applying security patches diligently, and using robust anti-malware and intrusion detection software on individual servers. Application security focuses on secure coding practices, vulnerability scanning, and Web Application Firewalls (WAFs) to protect against application-specific attacks. Least privilege access controls ensure that users and applications only have the minimum permissions necessary to perform their functions, reducing the attack surface and increasing the stability of each server by preventing unauthorized changes.
Compliance and Auditing
You’re often bound by regulatory requirements, and modern data centers are built to facilitate compliance. This involves a continuous cycle of auditing, reporting, and adherence to industry standards.
Regulatory Adherence
You benefit from data centers that are certified against various global and industry-specific compliance standards such as ISO 27001 (information security management), SOC 1/2/3 (Service Organization Control reports for financial reporting and security), HIPAA (health data), GDPR (data privacy), and PCI DSS (payment card industry data security). These certifications indicate that the data center has robust processes and controls in place to protect data and ensure service integrity. This adherence translates directly to a more secure and therefore more stable and trustworthy environment for your applications.
Comprehensive Logging and Auditing
You’re supported by extensive logging across all systems – network devices, servers, security appliances, and even physical access logs. These logs are aggregated, analyzed, and securely stored for long periods. This comprehensive logging provides an immutable audit trail, essential for compliance investigations, forensic analysis in case of a breach, and proving adherence to regulatory requirements. Regular internal and external audits review these logs and processes to ensure ongoing compliance and identify any potential weaknesses, constantly reinforcing the security and stability of the data center environment. You have a transparent record of all activity, crucial for accountability and trust.
Data Governance and Data Loss Prevention (DLP)
You’re utilizing data governance policies that define how data is collected, stored, processed, and destroyed. Data Loss Prevention (DLP) solutions monitor data in motion and at rest to prevent sensitive information from leaving the controlled environment. This ensures that your critical data remains secure and compliant with regulations, preventing breaches that could lead to significant instability, reputation damage, and financial penalties. Modern data centers implement these solutions to provide a secure perimeter around your information, contributing to the overall integrity and trustworthiness of the services you rely on.
FAQs
What are the key features of modern data centers that enhance server stability?
Modern data centers incorporate advanced cooling systems, redundant power supplies, and robust physical security measures. These features help maintain optimal operating conditions for servers, reduce the risk of overheating, and ensure continuous power availability, all of which contribute to improved server stability.
How does virtualization contribute to server stability in data centers?
Virtualization allows multiple virtual servers to run on a single physical server, optimizing resource utilization and reducing hardware dependency. This flexibility enables better load balancing and failover capabilities, which enhance overall server stability by minimizing downtime and improving recovery times during failures.
What role does monitoring play in maintaining server stability in modern data centers?
Continuous monitoring of server performance, temperature, and power usage is crucial for identifying potential issues before they escalate. Advanced monitoring tools provide real-time data and alerts, allowing data center operators to proactively address problems, thereby maintaining server stability and preventing outages.
How do redundancy and failover systems improve server stability?
Redundancy and failover systems ensure that if one component fails, another can take over without interruption. This includes redundant power supplies, network connections, and storage systems. By having these backups in place, modern data centers can maintain server stability even during hardware failures or unexpected outages.
What impact does physical security have on server stability in data centers?
Physical security measures, such as biometric access controls, surveillance cameras, and secure server enclosures, protect data centers from unauthorized access and potential sabotage. By safeguarding the physical infrastructure, these security measures help prevent disruptions that could compromise server stability.

Add comment